

For a while my home server was a single machine running Docker Compose. It worked fine until it didn’t: one bad container update, and everything on that box went down together. No isolation, no rollback, no way to test changes without touching production. The obvious fix was to restructure it properly, so I did, and that restructuring became Project Aether.
The original goal was to migrate 34 Docker Compose services to a production-grade Kubernetes platform on one repurposed HP laptop. The goal that survived contact with a 12 GB machine is more realistic: run a handful of critical services on a local K3s cluster with GitOps, put everything else on an Oracle Cloud free-tier ARM host, and watch both from a small Google Cloud VM outside either of them. One monorepo manages all three.
This post is the series opener. It covers what I’m running on, how the architecture fits together, and the reasoning behind the major decisions. The rest of the series goes through each layer in detail.
The hardware #
The homelab side runs on one machine:
| Component | Spec |
|---|---|
| Model | HP notebook (repurposed, 2015) |
| CPU | Intel Core i3-5005U, 2 cores / 4 threads, 1.90 GHz |
| RAM | 12 GB DDR3 |
| Storage (OS) | 256 GB SSD – system disk, VMs, K3s nodes |
| Storage (data) | 500 GB HDD – ZFS pool, media library, backups |
| Network | Gigabit Ethernet + Tailscale |
| Hypervisor | Proxmox VE 9.2 |
Display and lid removed. It sits in a Thermaltake case for airflow and runs headless around the clock.
The i3-5005U is a 2015 Broadwell-U chip with a 15 W TDP. It has enough for this workload, but there is no headroom to waste. Every architecture decision in this project flows from that constraint.
Why Proxmox #
The first decision was what to run on bare metal.
The obvious alternative was Ubuntu with Docker directly on the host. That works, but it has a specific failure mode: everything shares one kernel and one root filesystem. A misbehaving container, a bad apt upgrade or a kernel panic takes down the whole machine, including the network stack and the remote access layer. There is no recovery without physical access.
Proxmox gives each workload its own VM boundary with its own kernel. A panic inside a K3s VM doesn’t affect anything else. More practically, Proxmox takes instant snapshots at the hypervisor level. Before a risky change I take a snapshot, apply the change, and roll back in seconds if something breaks. That’s worth more than the small cost of virtualisation overhead.
VMware ESXi was considered and dropped. Broadcom’s post-acquisition licensing closed the free tier, and its footprint on an i3 is heavier than Proxmox’s KVM/LXC hybrid.
Why not K3s directly on bare metal? #
This one comes up a lot. If the goal is a K3s cluster, why not install Ubuntu and run K3s on it? Skip the hypervisor, give the full 12 GB to the cluster, no overhead. It makes sense on paper.
The problem is that K3s on bare metal turns the host OS and the cluster into the same thing. Upgrade the kernel and you’re touching the cluster’s foundation. Misconfigure a CNI plugin and you can lose SSH to the machine entirely, with no management plane outside it to recover through. There’s no snapshot to roll back to. On a machine with no IPMI or remote KVM, that means carrying the laptop somewhere, plugging in a monitor, and hoping the damage is recoverable from a local console.
Proxmox sits between the hardware and K3s and gives that recovery path. Its management interface runs outside the K3s VMs, so it’s still reachable when the cluster is completely broken. The first time I misconfigured the Flannel CNI and knocked out inter-node communication, I rolled the control plane VM back in about 30 seconds and started again from a clean state.
There’s also the resource argument. The three K3s nodes get exactly the RAM they’re configured for (2 GB for the control plane, 3.5 GB for each worker), and the rest stays with the host. On bare metal, the host OS, K3s and every pod share one flat pool with no hard boundaries.
The last reason is practical: Proxmox works with Terraform through the bpg/proxmox provider, so provisioning VMs is code, not clicks. task tf:apply DIR=03-homelab rebuilds the nodes from the Cloud-Init template.
The overhead is real. The three VMs take about 9 GB of the 12 GB, leaving roughly 3 GB for Proxmox itself. On tighter hardware that trade-off might not hold. On this machine, it does.
Storage: two tiers, not one pool #
The laptop has two drives with very different characteristics, so the decision was how to use them (ADR-002).
The SSD is fast but small. The HDD has twice the capacity but mechanical seek times that would make the Kubernetes datastore miserable, because it’s sensitive to I/O latency. One pool would throttle either capacity or performance.
The split:
- SSD: Proxmox host OS, VM root disks, K3s node disks, container images, database working data
- HDD: media library, Proxmox
vzdumpbackups, and a ZFS pool for bitrot protection on cold data, including the local backup copies
A ZFS mirror across both drives was considered and rejected. A mirror runs at the speed of the slower drive and is capped at the size of the smaller one, which wastes the HDD’s capacity and the SSD’s speed at the same time.
The downside is that every disk assignment is explicit, and an explicit assignment can be explicitly wrong. In November an audit found that the backup jobs had been writing to /mnt/aether-pool/, a plain directory on the SSD, while the ZFS pool on the HDD was mounted somewhere else and held 1.48 MiB. The local backups were on the disk they were meant to protect against (INC-2026-007). Each backup path is now its own ZFS dataset on the HDD, and the jobs refuse to run if it isn’t mounted.
K3s over Talos and MicroK8s #
With Proxmox as the hypervisor, the next question was which Kubernetes distribution to run inside the VMs (ADR-003).
Talos was appealing. It’s API-driven, immutable and purpose-built for Kubernetes. But it removes SSH and replaces standard Linux tooling with its own API. On a single-operator homelab where part of the point is learning to debug Kubernetes, losing the ability to SSH into a node and look around is a real cost.
MicroK8s runs on snap packages and is tied closely to the Canonical ecosystem. K3s is more common in real edge deployments and maps more directly to what small production environments run.
K3s won on three counts: a single binary with a small memory footprint, a standard Ubuntu VM with full SSH access, and skills that transfer to production edge clusters.
The cluster is three nodes: one control plane (2 vCPU, 2 GB) and two workers (2 vCPU, 3.5 GB each), running K3s v1.36. The control plane is initialised with --cluster-init, which swaps K3s’s default SQLite datastore for embedded etcd and enables k3s etcd-snapshot. Those snapshots feed a nightly backup chain that ends in an offsite, immutable copy.
The trade-off is that there’s no control-plane high availability. If the control plane VM dies, the API is unreachable until it comes back. And because all three nodes are VMs on one laptop, the hypervisor is a single point of failure for the whole cluster. That stopped being theoretical on 10 November, when the host panicked overnight and the cluster was down for nine hours (INC-2026-012). For a one-person homelab with good backups, that’s still an acceptable trade.
Tailscale for network access #
The homelab is behind a residential ISP in India. Most residential connections here use Carrier-Grade NAT, so there’s no public IP address to forward ports to, even if opening ports to the internet were a good idea. It isn’t.
The requirement was remote access from anywhere (SSH to the nodes, the Proxmox UI, the K3s API) without exposing anything publicly. Cloudflare Tunnels are built for publishing services to the internet, not for acting as a management VPN, and port forwarding was ruled out immediately.
Tailscale uses WireGuard and handles NAT traversal automatically, CGNAT included. Every node and operator device joins the same tailnet, and SSH, the Proxmox UI and the K3s API are reachable by MagicDNS name with no open ports on the router. The coordination server is the one dependency, and peers keep talking even if it goes down; new nodes just can’t join until it’s back.
Access between machines is granted by tag, and the tags are by role, not by location. That rule was learned the hard way: the tag that meant two things is the story.
Three environments #
| Environment | Hardware | Job |
|---|---|---|
| Homelab | The laptop: Proxmox + three K3s VMs | GitOps platform for the services that benefit from Kubernetes |
| Oracle Cloud app host | A1.Flex ARM, 2 OCPUs / 12 GB (Always Free) | Docker Compose apps, central metrics and logs |
| Google Cloud DMZ observer | e2-micro (Always Free), no public IPv4 |
Uptime Kuma and a public status page, watching everything from outside |
The observer is deliberately low-trust and lives in a different cloud from everything it watches, so it can raise the alarm when the rest of the platform can’t. It reaches the internet only over IPv6.
The full stack #
Homelab (Proxmox + K3s)
| Layer | Tool | Purpose |
|---|---|---|
| Hypervisor | Proxmox VE 9.2 | Bare-metal virtualisation, isolation, snapshots |
| IaC | Terraform + bpg/proxmox |
VMs cloned from the Cloud-Init template |
| State backend | GCS | Remote Terraform state for every module |
| Configuration | Ansible | K3s install, host hardening, backup jobs |
| Orchestration | K3s v1.36, embedded etcd | Lightweight Kubernetes |
| GitOps | ArgoCD (App-of-Apps) | Declarative delivery from Git |
| Load balancing | MetalLB | LAN addresses for services |
| Routing | Gateway API via Envoy Gateway | Replaces Ingress-NGINX |
| TLS | cert-manager, internal CA | Certificates for internal services |
| Secrets | SOPS + age + GCP Cloud KMS | Encrypted secrets in Git, either key decrypts |
| Network | Tailscale + Tailscale operator | Remote access and cross-environment links |
| Logs | Grafana Alloy | Ships pod logs to Loki on the app host (replaced Promtail in November) |
| Backups | etcd snapshots → restic on the HDD → Backblaze B2 | Nightly 3-2-1 chain with an immutable offsite copy |
| Task runner | Task | One command for every operation |
| CI | GitHub Actions, pre-commit | Every push and pull request runs the pre-commit gates (lint, secret and encryption checks), a Helm values lint and the tracked-files check; a nightly Terraform drift check |
Oracle Cloud app host
| Layer | Tool | Purpose |
|---|---|---|
| Compute | A1.Flex ARM, 2 OCPUs / 12 GB | Always Free instance |
| IaC | Terraform + oracle/oci |
Compute and storage |
| Configuration | Ansible | The whole Docker Compose stack |
| Apps | Docker Compose | n8n, AFFiNE, Navidrome, Blinko, IT-Tools, Kestra and more |
| Observability | Prometheus, Grafana, Loki, Alertmanager | Central metrics and logs for every environment |
| Tailnet access | tsdproxy | Each service is its own tailnet node, tagged by role |
Google Cloud DMZ observer
| Layer | Tool | Purpose |
|---|---|---|
| Compute | e2-micro |
Always Free, IPv6 for internet access |
| Monitoring | Uptime Kuma | External checks and Telegram alerts |
| Status page | Glance + Cloudflared | Public dashboard fed by a pushed summary, with no route back into the platform |
What is being migrated #
The original setup is 34 Docker Compose services, archived in legacy-docker/. After counting the real RAM budget on a 12 GB machine running K3s, trying to move all 34 locally is a guaranteed OOM failure.
The decision (ADR-010): move only the most critical few services to the local K3s cluster, and give everything else a permanent home on the Oracle Cloud host. The app host is permanent infrastructure, not an experiment. Each of its services is published on the tailnet, and all of them are deployed by Ansible.
The K3s cluster will host the services that benefit most from Kubernetes: self-healing, rolling updates and declarative recovery.
Where things stand (November 2026) #
- Phase 01, foundation: done. Proxmox, the Cloud-Init template, Terraform for all three environments with GCS state, the K3s cluster, Tailscale, SOPS with dual keys, and the Oracle Cloud app stack.
- Phase 02, GitOps: done. ArgoCD runs the App-of-Apps pattern, with sync waves and encrypted secrets decrypted in-cluster.
- Phase 03, platform: MetalLB, Envoy Gateway, cert-manager, the Tailscale operator and default-deny network policies are in Git and synced by ArgoCD. The etcd backup chain runs nightly, and a cold restore from the offsite copy has been drilled.
- Phase 04, applications: under way. On 17 November the first three apps (a notes app, a knowledge base and a developer toolbox) moved from the Oracle Cloud host to K3s, with their data checked row for row. They’re served through the gateway with Let’s Encrypt certificates, keep databases on a shared PostgreSQL and files on NFS, and back up nightly to an offsite Object Lock bucket. The rest stay on the cloud host, as planned.
There’s also a public, read-only status page with the platform’s live health, recovery objectives and incident history.
Along the way, the audits produced a set of incident reviews, each written up when its fix was verified. Several of them are the best material in this series.
Architecture #
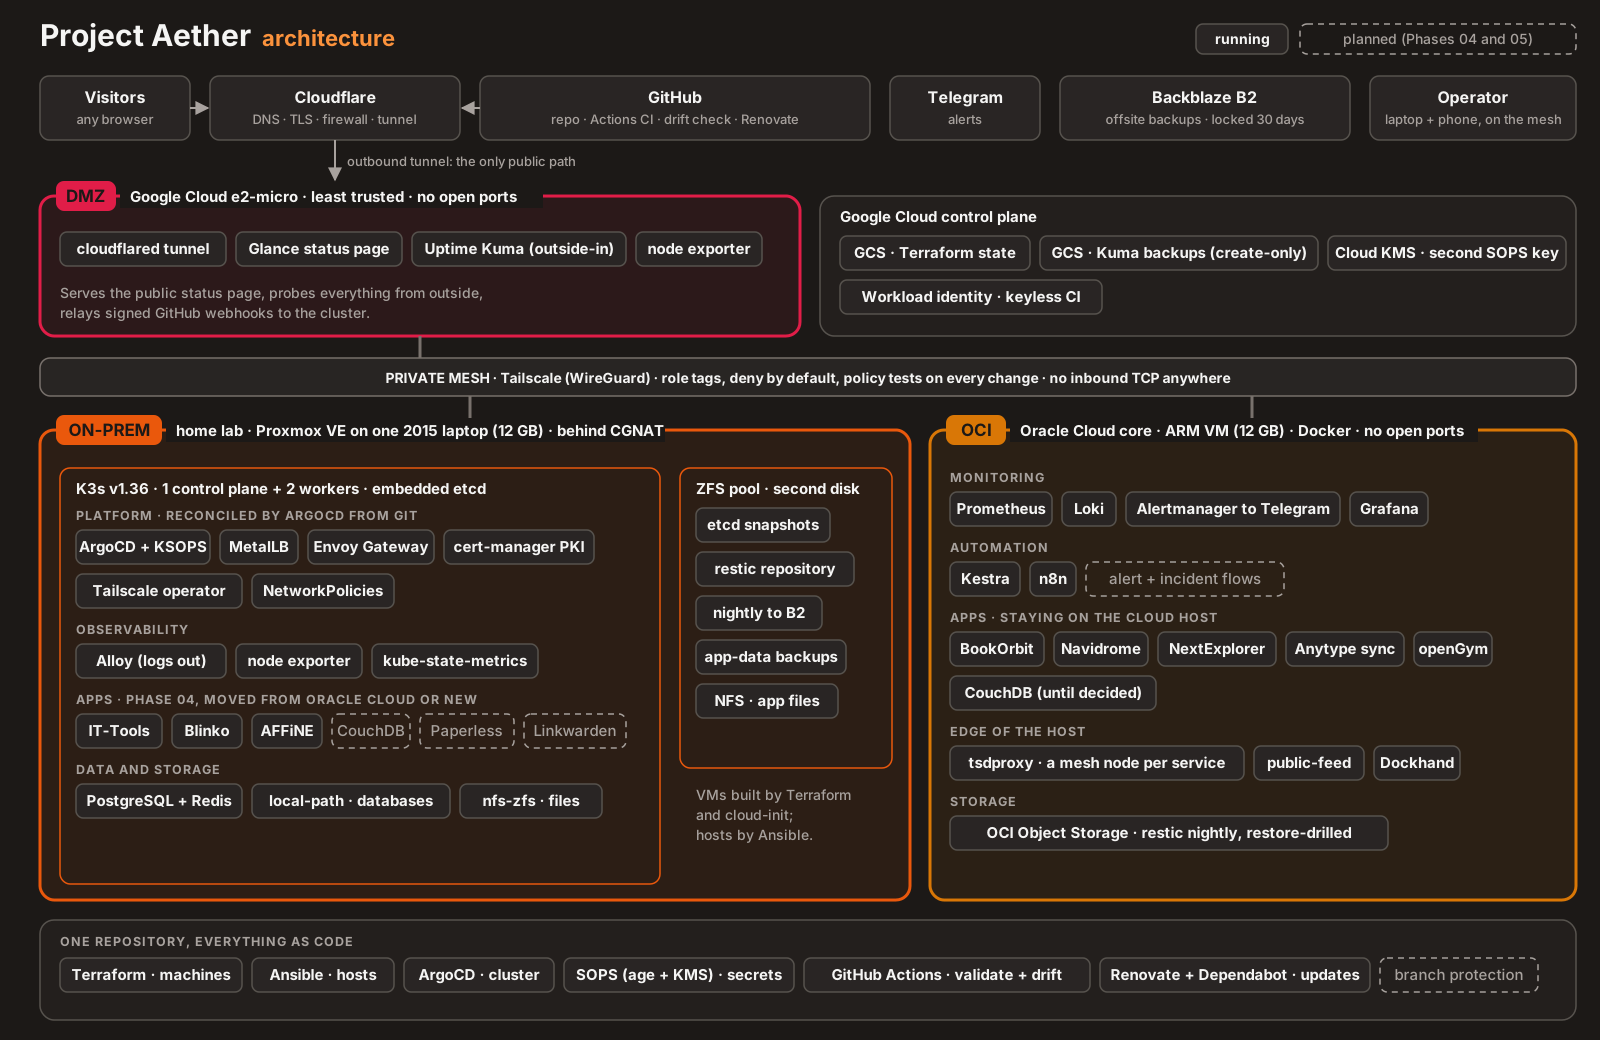
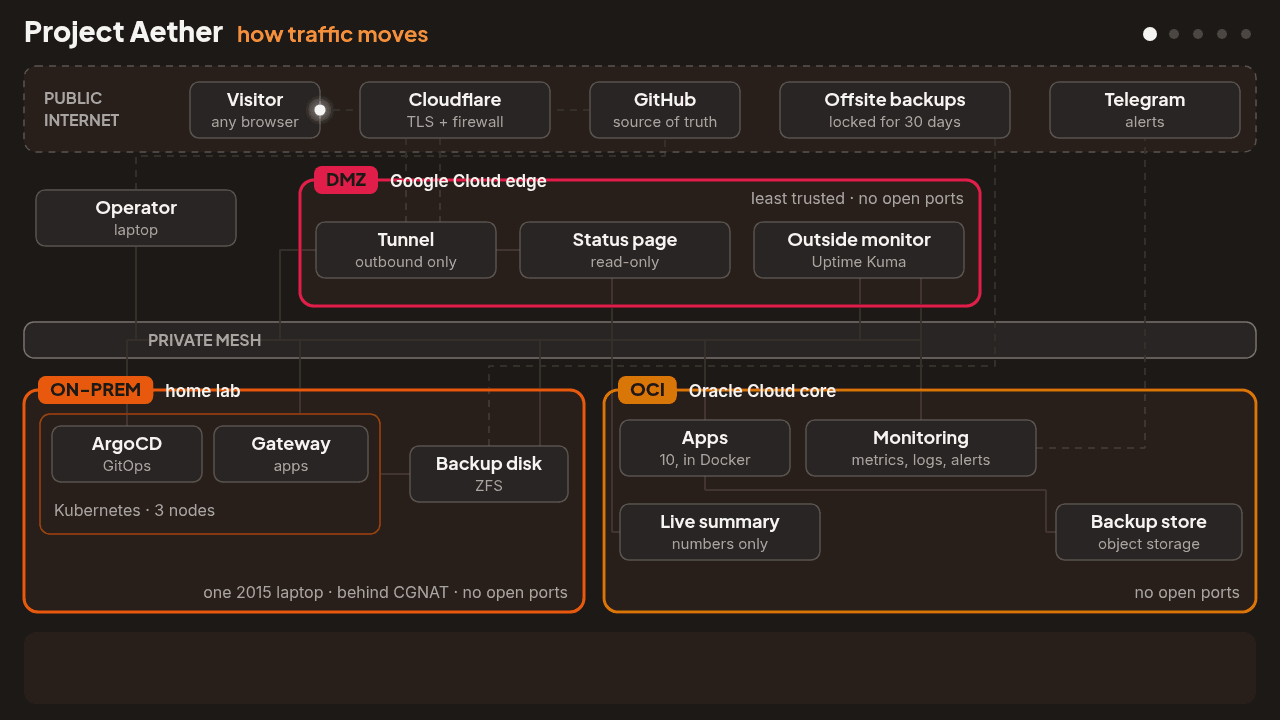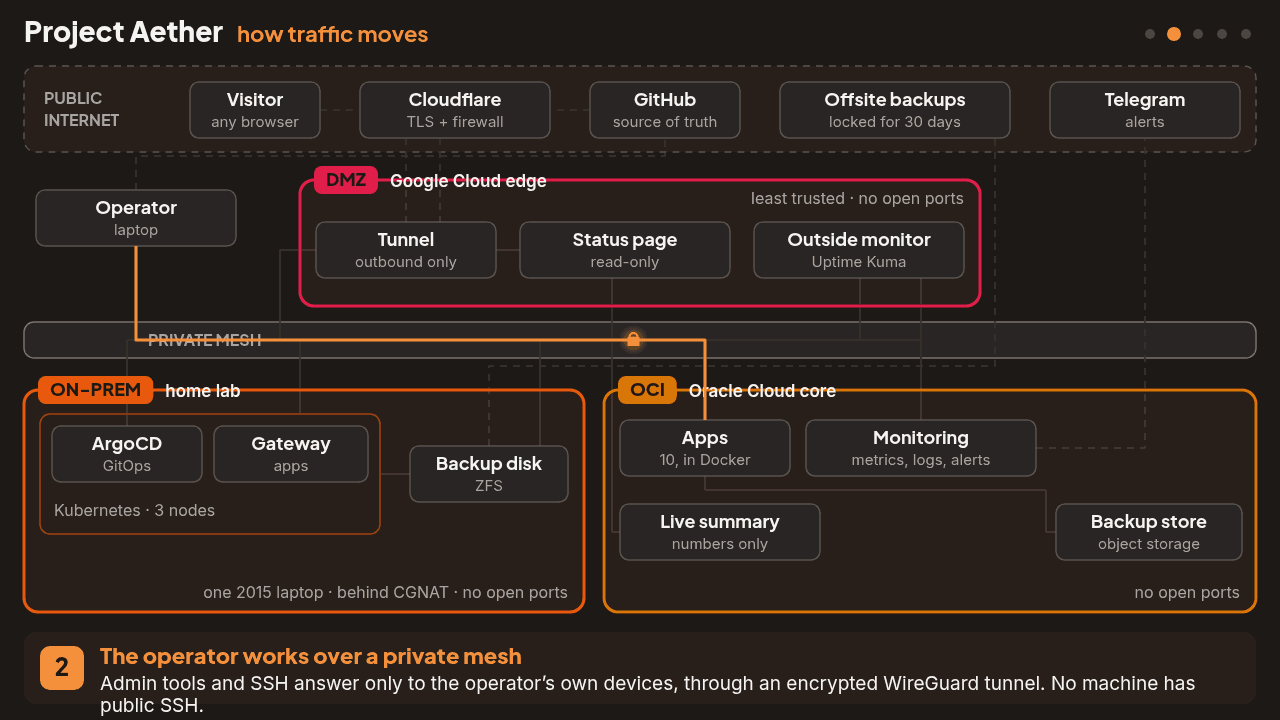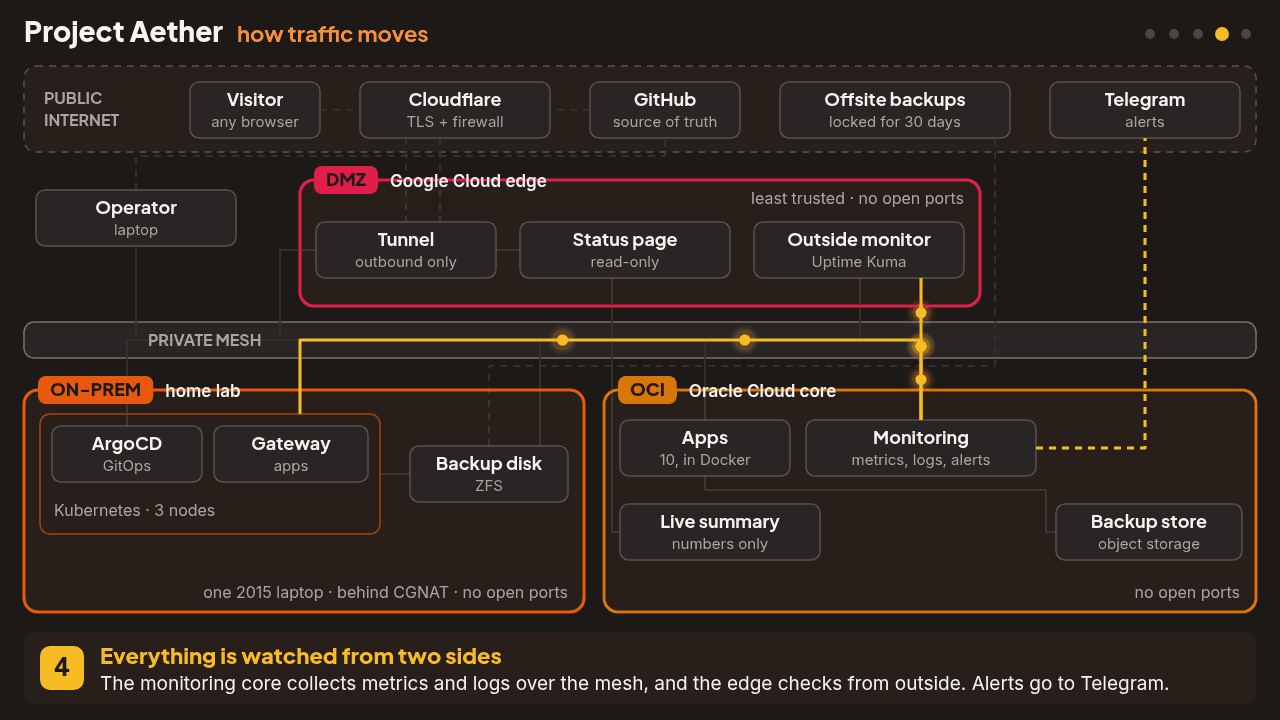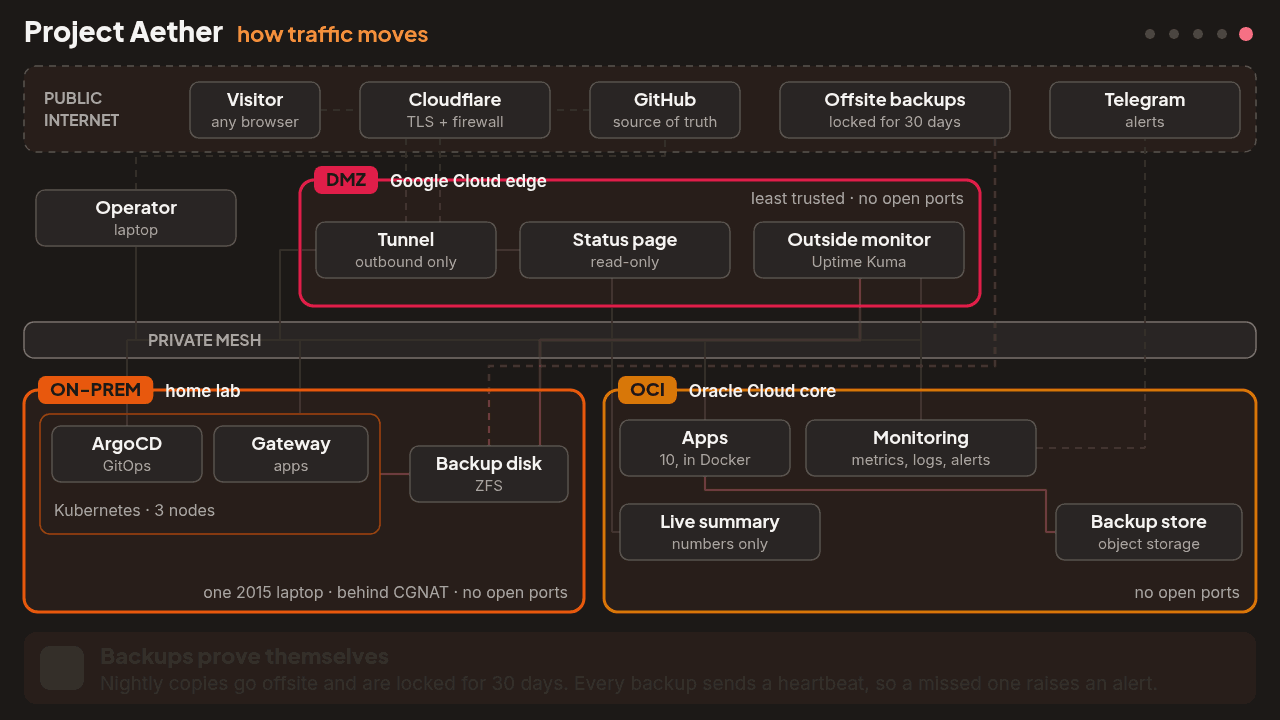
What I learned #
- Plans should shrink when the numbers come in. “Move all 34 services to Kubernetes” didn’t survive a RAM budget, and the three-environment design is better for it.
- A design document says what should be true; only a check says what is. The storage split was right on paper while the backups sat on the wrong disk.
- Choosing a free tier means designing around its limits. The observer’s lack of public IPv4 shaped how its alerts get out, and the app host’s size shaped what runs there.
Architecture takeaways #
Put each workload where its failure is cheapest #
The laptop is one machine with no battery and no remote power control. The cloud hosts are someone else’s hardware, but small. So the heavy, always-on apps went to the cloud host with the most memory, and the cluster keeps the few services where Kubernetes features pay for the risk. Placement followed blast radius, not preference.
Watch from outside the failure domain #
A monitor that runs on the thing it monitors goes down with it. The observer runs in a different cloud, on different hardware, with a deliberately narrow view: it can probe a few services on 443 and nothing else. When the hypervisor froze on 10 November, the alerts came from machines outside it, and reached my phone within four minutes.
On one host, recovery beats redundancy #
With one physical machine, real high availability isn’t on the table. What is affordable is fast, tested recovery: snapshots before risky changes, nodes rebuilt from a template by Terraform, and a nightly etcd backup chain with an offsite copy that has actually been restored. That’s where the effort went.
What’s next #
The next posts go layer by layer: the Cloud-Init template that every node is cloned from, the hardware mysteries of running a 2015 laptop as a 24/7 server, and the incident stories from November.